Matthew Gonzalez
Introduction
Deploying artificial intelligence (AI) models in production requires more than developing and training them. Businesses also need an efficient way to serve predictions, manage incoming requests, and use computing resources effectively. NVIDIA Triton Inference Server is an open-source inference-serving solution designed to help organizations deploy and run machine learning models across different environments.
Triton supports models from multiple frameworks, including TensorRT, ONNX, PyTorch, and TensorFlow, subject to the relevant back-end and version requirements. It can run on CPUs and supported GPUs, making it useful for applications involving computer vision, natural language processing, recommendation systems, and other AI workloads.
How Does NVIDIA Triton Inference Server Work?
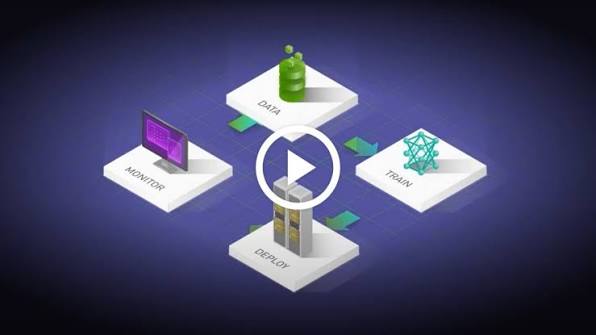
Triton acts as a serving layer between AI models and the applications that use them. It receives inference requests, executes the appropriate model, and returns the results to the requesting application.
Its main capabilities include:
1. Multi-Framework Model Support:
Developers can serve models from different supported frameworks through a common inference platform, reducing the need to build separate serving systems for each model type.
2. Dynamic Batching:
Triton can combine compatible inference requests into batches to improve throughput and hardware utilization. This is particularly useful when applications process many requests.
3. Concurrent Model Execution:
The server supports configuring multiple model instances and executing workloads concurrently, helping teams manage inference demand more effectively.
4. Multiple Communication Protocols:
Triton provides HTTP and gRPC interfaces, allowing applications to send inference requests using widely adopted communication methods.
5. Model Management:
Its model repository and configuration options help developers organize, load, and manage models deployed in production environments.
When Should You Use NVIDIA Triton Inference Server?
Triton is particularly useful when an organization needs a flexible and scalable system for serving machine learning models.
1. Deploying Multiple AI Models
If an application relies on several models, Triton can provide a common serving environment for supported models from different frameworks. This can simplify deployment architecture and reduce operational complexity.
2. Handling High Inference Workloads
Applications that process large numbers of requests may benefit from batching, concurrent execution, and configurable model instances. Examples include image analysis services, product recommendation engines, and real-time content processing systems.
3. Improving GPU Resource Utilization
For GPU-intensive applications, Triton offers configuration options that help teams manage model execution and improve hardware utilization. Performance testing remains essential because results depend on the model, workload, and available hardware.
4. Supporting Production AI Applications
Triton can serve as part of an inference infrastructure for applications that need consistent model-serving interfaces, predictable deployment configurations, and integration with monitoring and orchestration systems.
When Might Triton Not Be Necessary?
Triton may introduce unnecessary complexity for small projects that serve a single lightweight model with limited traffic. In these cases, a framework’s built-in inference capabilities or a simpler serving solution may be sufficient.
Teams should also consider operational requirements, hardware compatibility, model support, and the expertise needed to configure and maintain the server.
Conclusion
NVIDIA Triton Inference Server provides a flexible approach to deploying machine learning models in production. Its multi-framework support, dynamic batching, concurrent execution, and standard communication interfaces make it valuable for organizations managing demanding AI inference workloads.
Before adopting Triton, evaluate your model requirements, expected traffic, latency targets, and infrastructure. Choosing an inference-serving solution that matches these needs can help improve application performance while keeping deployment and maintenance manageable.